
dev-tools
Soul AI: An Open-Source Consciousness Simulator
Soul AI pairs a consciousness simulator with an Apache-2.0 model on Hugging Face, runnable through llama.cpp, plus a private offline iPhone companion app.
#ai#local-llm#llama-cpp
Tag
11 posts tagged #local-llm
Browse 11 posts tagged Local LLM. Setup notes, reviews, comparisons, and workflow patterns.
Soul AI pairs a consciousness simulator with an Apache-2.0 model on Hugging Face, runnable through llama.cpp, plus a private offline iPhone companion app.
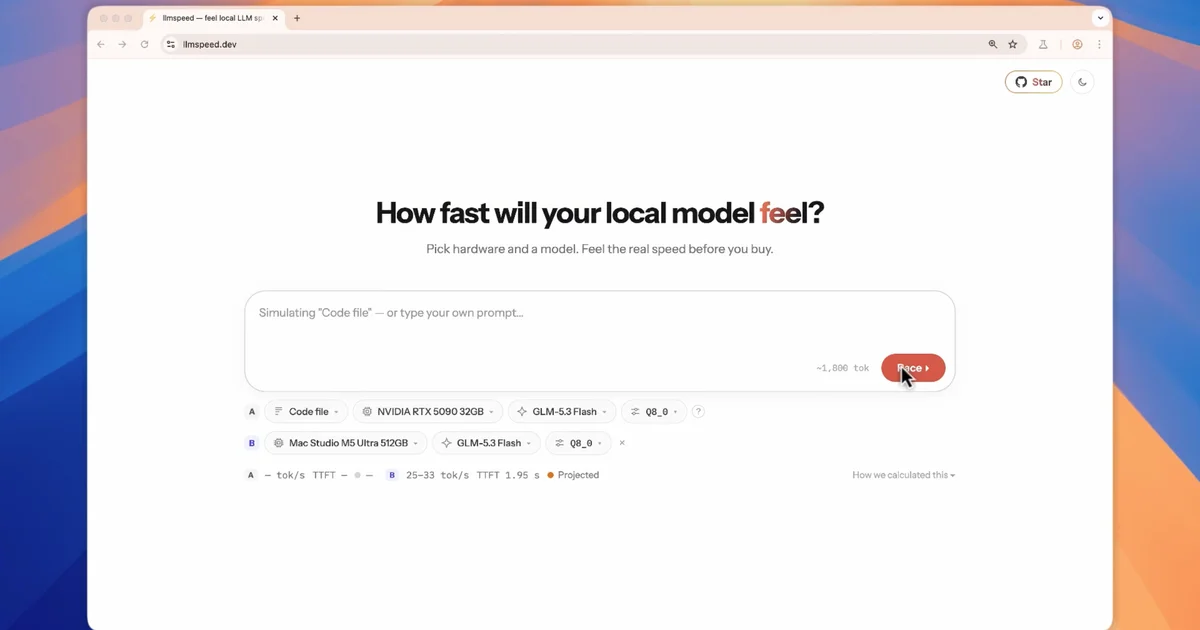
llmspeed simulates tokens per second and time-to-first-token for local LLMs across 30 GPUs, Macs and CPUs, so you can judge hardware before buying.
AirLLM runs 70B-parameter models on a single 4GB GPU. Here is what the repo claims, what the numbers imply, and where the approach breaks down.

ds4 is an MIT licensed C implementation of DeepSeek 4 Flash and PRO local inference, targeting Metal, CUDA and ROCm with 23,453 GitHub stars.

Wolffish is a local-first AI desktop agent that runs entirely on your machine with no cloud dependency. Built with a 15-module brain architecture, markdown-driven behavior, and full system access on
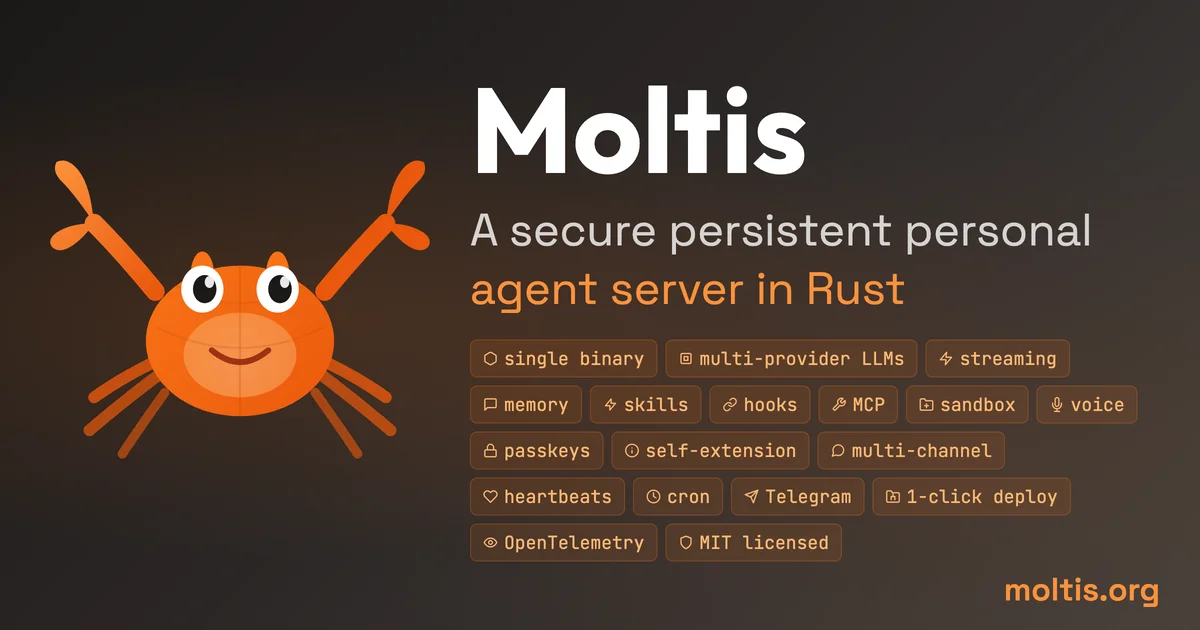
Moltis is a self-hosted AI agent server written in Rust. One binary, sandboxed tool execution, multi-provider LLMs, voice, memory, and integrations with Telegram, Discord, and MCP tools.
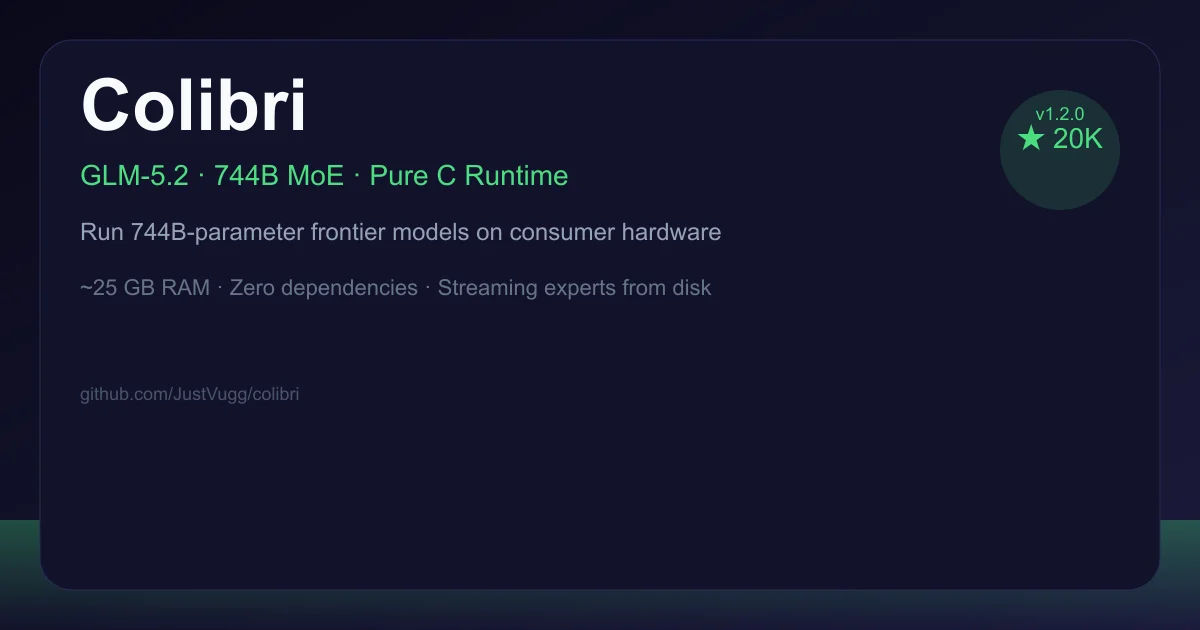
Colibri is a pure-C MoE runtime that streams 744B-parameter GLM-5.2 from disk to consumer hardware. Zero Python, zero GPU required — ~25 GB RAM and you are running a frontier model locally.
Phi-3-MLX brings Microsoft's Phi-3.5-vision and Phi-3.5-mini models to Apple Silicon Macs via MLX. Install with pip and run locally in minutes.
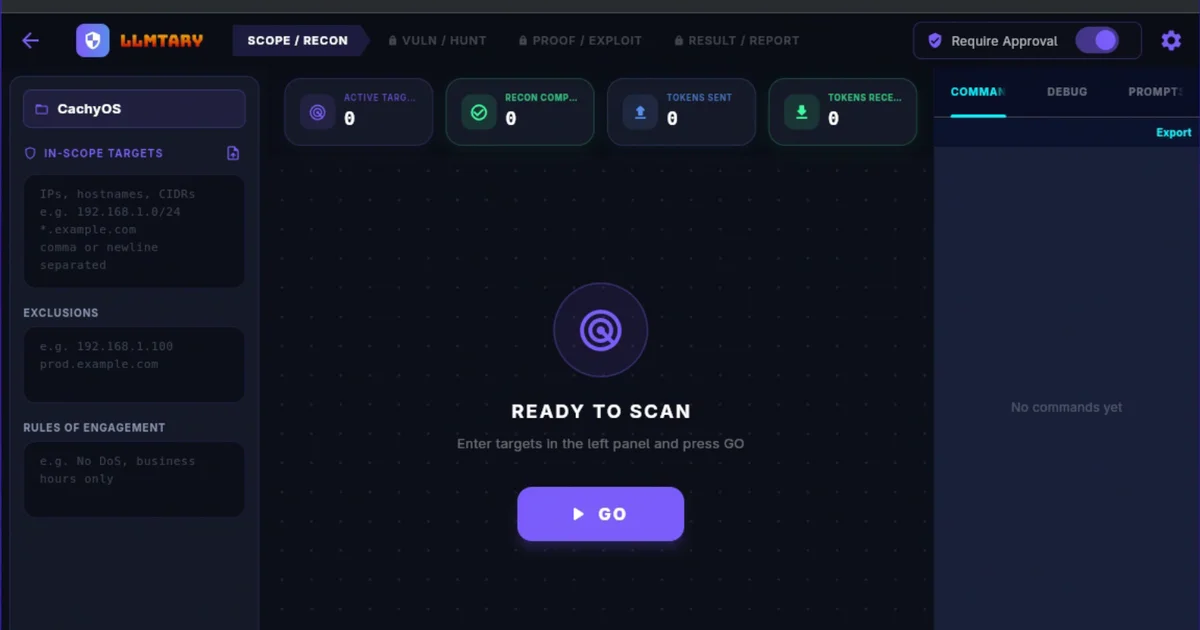
Run autonomous penetration tests with local LLMs. LLMtary chains recon, exploitation, and reporting—Ollama, Claude, GPT-4, and Gemini supported.
Bodhi App is a free, open-source desktop app that runs open-source LLMs locally on macOS, Windows, or Linux with an OpenAI-compatible API and built-in Chat UI.
Instantly check whether your PC can run open-source LLMs like Llama, Mistral, and Gemma locally. Get personalized GPU/VRAM requirements and quantization recommendations.