FeyNoBg: open-source background removal you can train
Open-source background removal model from Feyn Labs, plus NoBg, the Python library used to train it. Tops four of eight segmentation benchmarks.
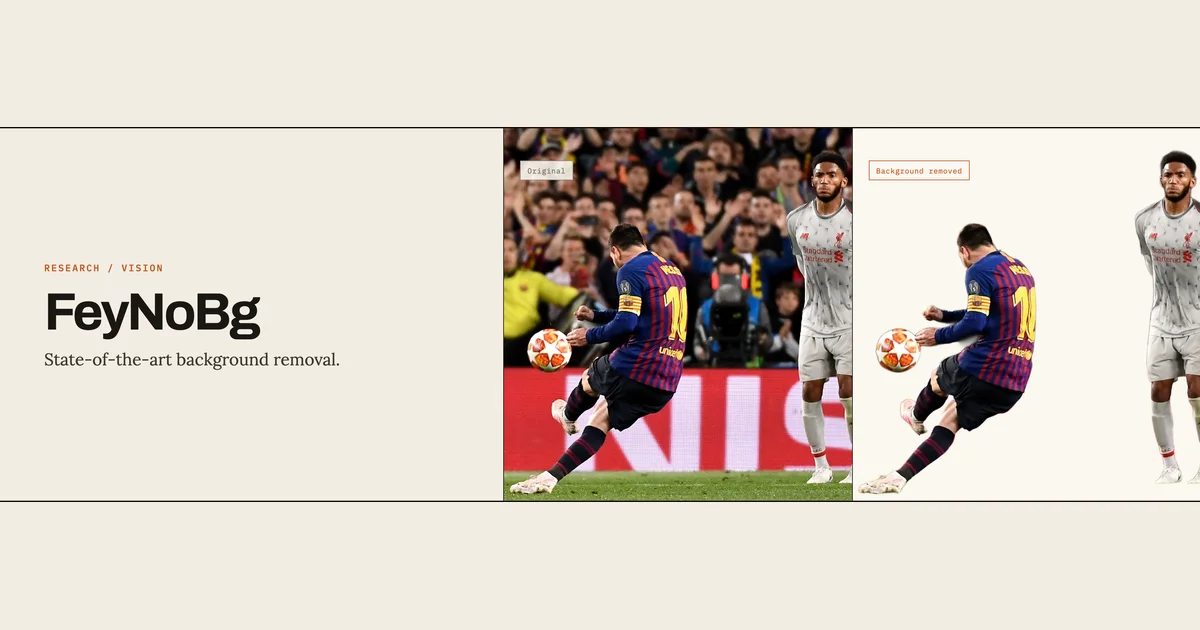
TL;DR: Feyn Labs released FeyNoBg, an open-source background removal model, together with NoBg, the Python library the team used to train it. The model posts the best published S-measure on four of eight segmentation benchmarks and lands within 2% of the leader on the other four, and NoBg gives you one interface for running the released weights or fine-tuning them on your own image and mask pairs.
What Feyn actually shipped
Background removal sounds like a solved problem. It is not, and the reason is that two separate skills hide behind the word “remove”. The first is recognizing which pixels belong to the subject. The second is deciding how opaque each boundary pixel should be, which is the actual hard part, because hair, fur, thin wire and motion blur all straddle the edge.
Feyn Labs, a YC-backed team in San Francisco, published a model called FeyNoBg for this, plus NoBg, the Python library they used to train it. Both are open source under Apache-2.0. Weights are on Hugging Face as feyninc/FeyNobg, and the library lives at github.com/feyninc/nobg.
The library has around 169 stars and the model card shows roughly 14,600 downloads, which for a niche vision model released in July 2026 is not nothing. There is also a hosted demo at usefeyn.com/multimatte if you want to try the model without touching Python.
Why training mix is the hard part
The two skills are usually taught with different kinds of focused data. Foreground recognition datasets look one way, matting datasets look another. Feyn’s framing is that this creates a failure point: a model trained on a narrow mix ends up unbalanced, where gains in one skill come at the cost of the other. Outputs either clip parts of the subject or leave ragged edges.
Their fix was to widen the mix rather than add capacity for its own sake. The authors report that this broader mix turned an early regression on DIS5K into one of their four benchmark wins, which suggests the bottleneck was coverage of the skill combination, not raw model size.
That is the part worth remembering even if you never install the weights. Most matting models are not short of parameters. They are short of training data that asks for recognition and boundary precision at the same time.
The benchmark numbers
Here is the S-measure table as the authors published it, with the strongest published competitor on each benchmark for comparison.
| Benchmark | FeyNoBg | Runner-up | Gap |
|---|---|---|---|
| UHRSD-TE | 0.981 | BiRefNet 0.957 | +2.5% |
| HRSOD-TE | 0.983 | S3ODNet 0.961 | +2.3% |
| DIS5K | 0.961 | FlowDIS 0.951 | +1.1% |
| DAVIS-S | 0.977 | BiRefNet 0.975 | +0.2% |
| DUTS-TE | 0.941 | S3ODNet 0.949 | -0.8% |
| COD10K-TE | 0.912 | S3ODNet 0.923 | -1.2% |
| DUT-OMRON | 0.883 | S3ODNet 0.898 | -1.7% |
| CAMO-TE | 0.887 | BiRefNet 0.904 | -1.9% |
The shape of that table is more informative than the headline. FeyNoBg wins on the high-resolution salient-object sets and loses on the camouflage-heavy ones, where the subject is designed to blend into its surroundings. COD10K, DUT-OMRON and CAMO all test exactly that, and S3ODNet, a model trained heavily on synthetic data, holds them.
Two caveats on reading this table. The comparison is against published numbers from other papers rather than a single re-run of every model on one machine, so protocol differences between labs are baked in. And all eight are segmentation benchmarks; none of them is a matting benchmark, where boundary quality is scored directly.
What changed inside BiRefNet
FeynNoBg is built on BiRefNet, the 2024 model by Zheng and colleagues, which splits the work in two: a localization module finds the foreground, and a reconstruction module traces its boundary. Both consume feature maps from a four-stage Swin transformer extractor.
The third stage of that extractor is the one that has to reason about the whole subject while keeping enough spatial detail to draw its shape, so Feyn deepened it from 18 blocks to 24 and injected six fresh blocks on top of the pretrained weights. The base configuration is depths=[2, 2, 18, 2]; the growth takes the model from 222M parameters to 263M.
A 41M parameter increase is a modest patch on top of pretrained weights, not a new architecture. The interesting claim is that the extra depth and the wider training mix together were what moved the numbers, and separating those two contributions would take a rerun the authors did not publish.
Running the model
The library installs from PyPI:
pip install nobgInference resizes and normalizes the image, runs the model, converts the output into an alpha matte at the original resolution and writes a transparent PNG.
import torch
from loadimg import load_img
from nobg import AutoModel, AutoProcessor

model = AutoModel.from_pretrained("feyninc/FeyNobg").eval()
processor = AutoProcessor.from_pretrained("feyninc/FeyNobg")

image = load_img("input.jpg").convert("RGB")
inputs = processor(image, return_tensors="pt")

with torch.inference_mode():
    outputs = model(pixel_values=inputs["pixel_values"])

alpha = processor.post_process_alpha_matting(
    outputs,
    target_sizes=[(image.height, image.width)],
)[0]

processor.cutout(image, alpha).save("output.png")
Training is where NoBg earns its keep, because it gives you the model, the processor and the loss as one package rather than three separate repos that need adapters written between them. It plugs into the Hugging Face Trainer, which handles the loop, checkpointing and evaluation.
from nobg import AutoModel, AutoProcessor
from transformers import Trainer, TrainingArguments

model = AutoModel.from_pretrained("feyninc/FeyNobg")
processor = AutoProcessor.from_pretrained("feyninc/FeyNobg")

def collate(examples):
    batch = processor(
        images=[example["image"] for example in examples],
        segmentation_maps=[example["mask"].convert("L") for example in examples],
        return_tensors="pt",
    )
    return {
        "pixel_values": batch["pixel_values"],
        "labels": batch["labels"],
    }

trainer = Trainer(
    model=model,
    args=TrainingArguments(output_dir="outputs", learning_rate=2e-5),
    train_dataset=dataset,
    data_collator=collate,
)
trainer.train()
The dataset there is a Hugging Face Dataset with image and mask columns. NoBg does not ship a dataset builder or a synthetic data pipeline, so producing masks for your own domain is still work you own.
NoBg against the original BiRefNet
The team also benchmarked its own BiRefNet implementation inside NoBg against the upstream one, and reported better numbers on all three axes at every batch size.
| Batch size | Throughput (img/s) | Latency (ms/img) | Peak GPU (MB) |
|---|---|---|---|
| 1 | 1.14 vs 0.87 | 878 vs 1,146 | 3,046 vs 3,196 |
| 2 | 1.07 vs 0.89 | 932 vs 1,123 | 5,229 vs 5,532 |
| 4 | 0.97 vs 0.88 | 1,036 vs 1,135 | 9,600 vs 10,206 |
Each cell is NoBg first, upstream second. The throughput gap is the largest, roughly 30% faster at batch size 1, which is where the interface overhead matters most. The memory savings are real but modest, in the low single-digit percentages.
What to watch for
The practical constraint is size. At 263M parameters this is a GPU workload, and the throughput numbers above are per-batch on hardware with room to spare. A 263M-parameter matting network running at about one image per second is not something to put in a browser tab or on a phone, and NoBg’s own demo is a server-side path.
The camouflage results are the other thing to sit with. If your photos involve animals blending into grass, patterned fabrics, or similar, the benchmark suggests S3ODNet and BiRefNet are the safer defaults rather than the leader Feyn claims. The four wins are on high-resolution salient-object datasets, which describes a lot of product photography and stock imagery but not every use case.
And the weights are a showcase. Feyn sells matting inside its own product, and this release is written as a research field note from a commercial lab. The benchmark table is not independently reproduced in the post, so treat the exact ordering as the authors’ claim and the released artifacts as the part you can verify yourself.
Source and Accuracy Notes
- Project page: https://usefeyn.com/blog/feynobg/, verified via direct visit on 2026-10-30
- Model weights: https://huggingface.co/feyninc/FeyNobg, license apache-2.0, about 14,676 downloads at time of check
- Source repository: https://github.com/feyninc/nobg, license Apache-2.0, Python, 169 stars, last push 2026-08-26
- Online demo: https://usefeyn.com/multimatte
- Base architecture: BiRefNet, Zheng et al., “Bilateral Reference for High-Resolution Dichotomous Image Segmentation”, arXiv:2401.03407
- Benchmark values are as published by the authors and were not independently re-run
- HN launch thread: https://news.ycombinator.com/item?id=49072462, 121 points on 2026-07-27
Related Posts
dev-tools
Automotive Skills Suite for AI Engineering
Evaluate Automotive Skills Suite for APQP, ASPICE, HARA, safety-plan, and DIA workflows with setup notes, governance risks, and SME review guidance.
5/28/2026
dev-tools
awesome-agentic-ai-zh Roadmap Guide
Explore awesome-agentic-ai-zh as a Chinese agentic AI learning roadmap, with setup notes, track selection, study workflow, and evaluation guidance.
5/28/2026
dev-tools
Baguette iOS Simulator Automation Guide
Set up Baguette for iOS Simulator automation, web dashboards, device farms, gesture input, streaming, and camera testing with Xcode caveats.
5/28/2026